 The Executive
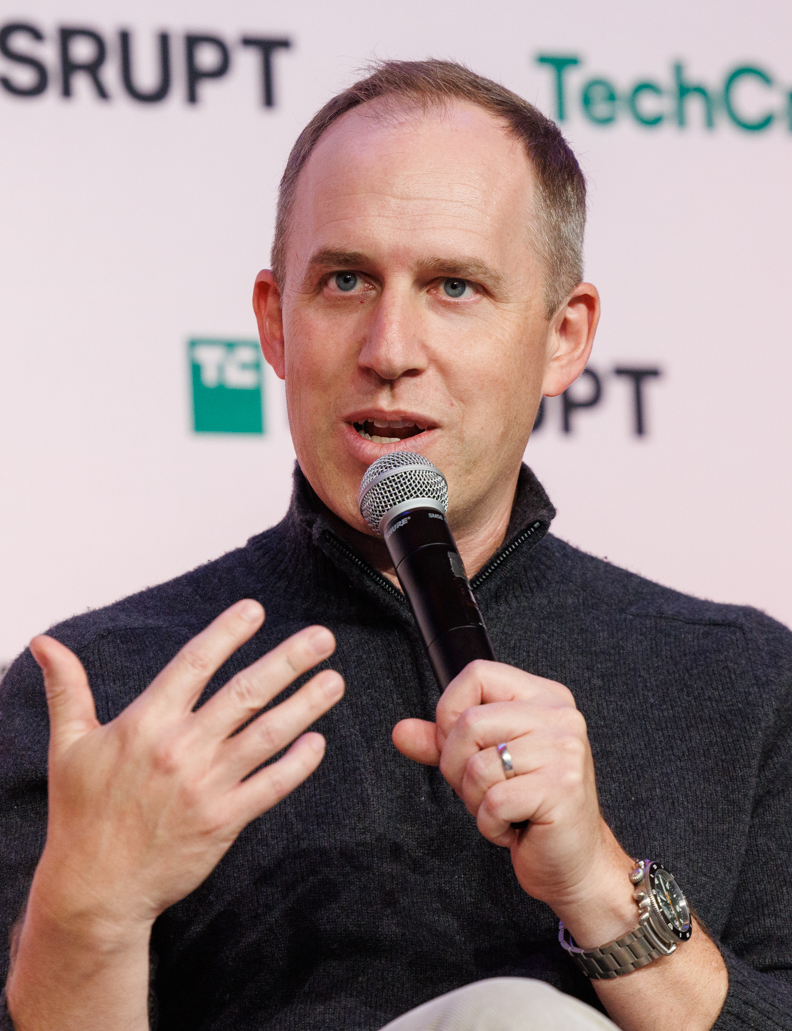
Josh Wills
The data engineer who built Slack's data engineering team and created the dbt-duckdb adapter now works on automated training-data selection for AI models.
Where he works now
Josh Wills is a member of technical staff at DatologyAI. He has held that position since 2024, according to a MotherDuck interview, and the work centers on tools that automatically select training data for deep learning models, along with distributed pipelines that process data at the scale of trillion-token pretraining runs. He is also building an index over datasets to work out which data assets can be reused.[1]
DatologyAI describes itself as a data curation company for AI model builders. It refines a customer's data into training data, deployed on the customer's own cloud, and says it does not sell data or source tokens. Its site lays out a four-stage process of cleaning, calibrating, creating synthetic data and composing data mixes, and it publishes two customer results: a Thomson Reuters legal-domain mid-training study and an Arcee model trained on Datology-curated data. Those are company claims, and the page itself gives inconsistent token counts for the Arcee run, so they are noted here only as context for the kind of work his team supports.[5]
Google and Cloudera
Wills describes about 25 years as a software and data engineer. He was a staff engineer at Google from 2007 to 2011, where he worked on the ad auction system and led analytics infrastructure for Google+. He then moved to Cloudera, the enterprise data company, where he was head of data science.[1]
At Cloudera he founded the Apache Crunch project and co-authored the O'Reilly book Advanced Analytics with Spark. The UC Berkeley DataEDGE conference page that lists him as a 2016 speaker also credits him as founder of Apache Crunch and co-author of that book, and records his May 6, 2016 session on bridging data engineering and data science.[1][4]
Building data engineering at Slack
Wills was at Slack from 2015 to 2019, according to the MotherDuck interview, building and leading its data engineering team. The Berkeley page presents him as head of data engineering at Slack, and a January 2020 Software Engineering Daily episode describes him as the company's director of data engineering during a period of rapid scaling.[1][3][4]
That episode recounts why message search was so hard at Slack: very high message volume, highly sensitive content, strict separation so one customer's messages could never reach another, high availability, and indexing needs that outran the infrastructure during fast growth. It also covers how the company's early growth pulled in engineers from Facebook and Google, and how the two companies approach data engineering differently.[3]
Open source: dbt-duckdb
Wills is the original creator of the dbt-duckdb adapter, which lets the dbt transformation tool run on the DuckDB analytical database. MotherDuck's author page describes him as an engineer who created the adapter, previously worked at Slack and Cloudera, and contributes to open-source projects in the DuckDB ecosystem. Its list of his content includes a February 29, 2024 video on faster data pipelines with local development using DuckDB and dbt.[1][2]
Back to work after retirement
The MotherDuck interview adds a personal detail: he reportedly retired around 2022 and returned to work because of the AI boom, joining DatologyAI in 2024. He says he now uses DuckDB less in his day job, since the datasets he handles are huge and text-based rather than classical tables, and he reaches for Spark or Ray instead.[1]
Views on data engineering and AI agents
In the same interview he argues that data engineering is not going away, because its core problem is cache invalidation and materialization, now applied to batch processing. He expects AI models to converge in competence, making the choice between them mostly a matter of personal preference.[1]
On coding agents, he says they do best where feedback is fast, such as math, front-end work or SQL with query explain plans. Large Spark and Ray pipelines lack that loop, so agents tend to write costly, inefficient code there. In his view engineers become emergency exception handlers who step in when agents fail and concentrate on making and communicating design decisions and trade-offs, while agents take over tedious jobs such as flaky tests and database migrations. He also observes that fewer engineers now understand how data is laid out on disk or how to run large Spark clusters.[1]
Why he matters in data engineering
Few practitioners have worked on data at as many layers: the Apache Crunch project from his Cloudera years, a data engineering organization at a fast-growing messaging company, and an adapter used in the DuckDB ecosystem. His current focus on selecting training data for AI models applies the same discipline of curating and moving data at scale to a newer problem.[1][2][3]
On The Executive List
Josh Wills is ranked No. 23 on The Executive List (October 2026) in the Chief Data Officers discipline. The list row shows his former Slack role; he is now at DatologyAI. The ranking reflects The Executive Review's own editorial Trending Score; it is not an outside award, and placement on the list is never sold. View the October 2026 edition.
Sources
- MotherDuck - The cache invalidation problem in data engineering, with Josh Wills
- MotherDuck - Josh Wills (author page)
- Software Engineering Daily (Jan. 10, 2020) - Slack Data Platform with Josh Wills
- UC Berkeley DataEDGE - Josh Wills (speaker, 2016)
- DatologyAI - Company site
Profile compiled from the public sources above by The Executive Review editors. Last updated 2026-10-23.